eBPF vs iptables: Why Netfilter is a Bottleneck in 2026
eBPF replaces the traditional iptables networking stack in Kubernetes by...
Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

We use cookies for our website to give you the most relevant experience by remembering your preferences. By clicking “accept”, you consent to use of ALL the cookies
This website uses cookies to improve your experience while you navigate through the website. Out of these, the cookies that are categorized as necessary are stored on your browser as they are essential for the working of basic functionalities of the website. We also use third-party cookies that help us analyze and understand how you use this website. These cookies will be stored in your browser only with your consent. You also have the option to opt-out of these cookies. But opting out of some of these cookies may affect your browsing experience.
Necessary cookies are absolutely essential for the website to function properly. These cookies ensure basic functionalities and security features of the website, anonymously.
| Cookie | Duration | Description |
|---|---|---|
| cookielawinfo-checkbox-functional | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category “Analytics”. |
| cookielawinfo-checkbox-functional | 11 months | The cookie is set by GDPR cookie consent to record the user consent for the cookies in the category “Functional”. |
| cookielawinfo-checkbox-necessary | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookies is used to store the user consent for the cookies in the category “Necessary”. |
| cookielawinfo-checkbox-others | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category “Other. |
| cookielawinfo-checkbox-performance | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category “Performance”. |
| viewed_cookie_policy | 11 months | The cookie is set by the GDPR Cookie Consent plugin and is used to store whether or not user has consented to the use of cookies. It does not store any personal data. |
Functional cookies help to perform certain functionalities like sharing the content of the website on social media platforms, collect feedbacks, and other third-party features.
Performance cookies are used to understand and analyze the key performance indexes of the website which helps in delivering a better user experience for the visitors.
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics the number of visitors, bounce rate, traffic source, etc.
Advertisement cookies are used to provide visitors with relevant ads and marketing campaigns. These cookies track visitors across websites and collect information to provide customized ads.
Other uncategorized cookies are those that are being analyzed and have not been classified into a category as yet.
Cyberia Tech, Inc. respects your privacy. This Privacy Policy explains how we collect, use, and share your information. By using our services, you agree to this policy. If any other agreements conflict with this Privacy Policy, the terms of those agreements prevail.
Cyberia Tech complies with the EU-US and Swiss-US Privacy Shield Frameworks for handling personal data from the EEA, UK, and Switzerland. In case of any conflict, the Privacy Shield Principles prevail. Learn more at Privacy Shield. Key Definitions
Information linked to an individual, transferred from the EEA, UK, or Switzerland to the U.S.
Data revealing race, religion, health, sexual orientation, and similar categories.
Effective Date: [ 2026 / 10 / 18 ]
Welcome to The Cyberia Tech ! By accessing or using our website or services, you agree to
comply with and be bound by these Terms of Use and our Privacy Policy. If you do not agree with
these terms, please do not use our Services.
Loading
0 %
Your First Piece of the Puzzle in
Business Growth


eBPF replaces the traditional iptables networking stack in Kubernetes by executing custom routing logic directly within the Linux kernel, bypassing netfilter entirely. While iptables parses rules sequentially at O(n) complexity, eBPF uses O(1) hash maps, reducing CPU overhead by up to 70% in high-traffic web applications.
Network overhead is the silent killer of node utilization. When a web application scales past 5,000 internal services, traditional kube-proxy routing begins to consume compute cycles just calculating where packets should go. The O(n) complexity of netfilter rules means that every new microservice incrementally degrades cluster throughput. Migrating away from this legacy architecture involves fundamental decisions about how packets traverse the kernel. You must evaluate whether the reduction in latency justifies the strict kernel version requirements and complex observability tooling necessary for an eBPF deployment.
Traditional Kubernetes networking relies on iptables to manage pod-to-pod and external traffic. This system operates as a packet filtering framework built on top of the netfilter hooks inside the Linux kernel. Traffic traverses a rigid sequence of hooks: PREROUTING, INPUT, FORWARD, OUTPUT, and POSTROUTING. Kube-proxy injects complex Network Address Translation (NAT) rules into these chains to manage service load balancing. Every time a packet arrives, the kernel evaluates it against a sequential list of rules. At a small scale, this process is indistinguishable from zero-latency switching. However, as the routing table grows, parsing these rules sequentially consumes significant CPU cycles.
In contrast, eBPF (Extended Berkeley Packet Filter) allows developers to run sandboxed programs directly within the operating system kernel without modifying kernel source code or loading distinct modules. Tools like Cilium attach eBPF programs directly to sockets and network interface cards (NICs). Instead of traversing the entire TCP/IP stack and netfilter chains, an eBPF program evaluates the packet context and forwards it immediately based on internal maps.
By version 1.15, Cilium leverages a feature known as sockmap for local pod-to-pod communication. This mechanism intercepts traffic at the socket layer and redirects it directly to the destination socket residing on the same node. It bypasses the lower-level network stack completely, which prevents unnecessary memory allocations and context switches, resulting in up to 2.5x higher throughput for identical application workloads.
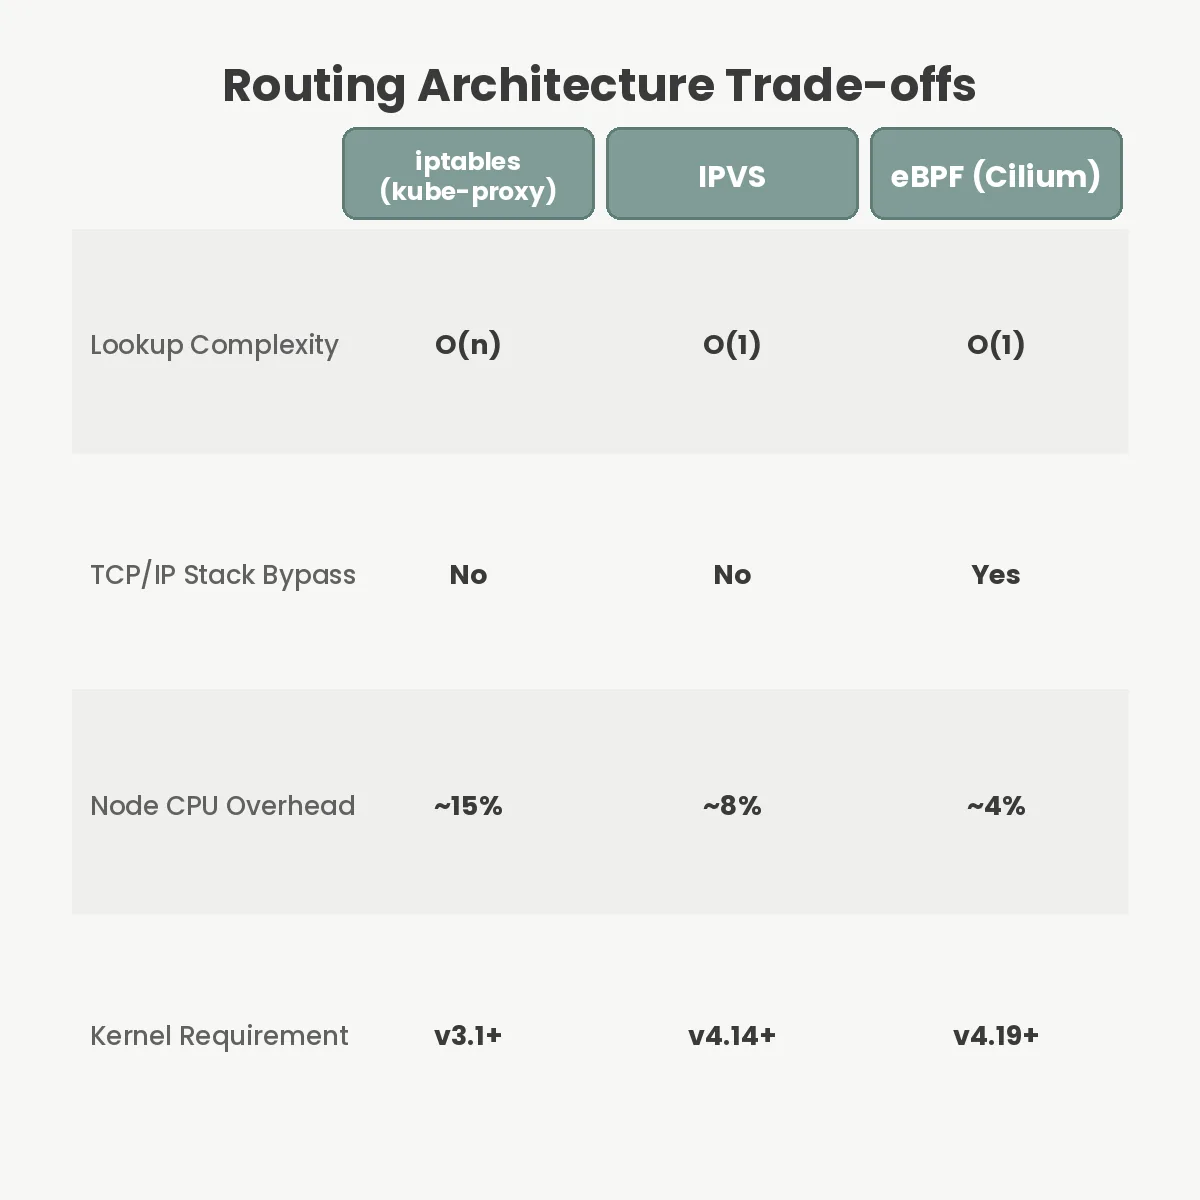
The primary constraint of iptables is its algorithmic complexity. Evaluating rules sequentially means performance degrades linearly, resulting in an O(n) lookup time. If a cluster defines 5,000 services, kube-proxy generates tens of thousands of iptables chains. Kube-proxy struggles to synchronize this state efficiently. A single service deployment can require the daemon to lock and rewrite the entire rule set, causing intermittent network disruptions and sharp CPU spikes across the worker nodes.
eBPF structures its routing tables using eBPF maps, which are highly efficient O(1) hash tables. Regardless of whether a cluster has 50 services or 50,000, the lookup time remains virtually constant. This architectural shift prevents the routing layer from becoming a computational bottleneck. Memory is allocated predictably, and updates to the routing tables happen atomically without locking the entire network path.
When maximizing bare-metal node utilization, reclaiming compute resources from the networking stack translates directly to higher application density. AWS EKS documentation from June 2025 details how Amazon deprecated native iptables kube-proxy dependencies for default cluster configurations. They prioritized their eBPF-powered VPC CNI extension precisely to minimize internal data transfer latency and reduce host-level CPU consumption.
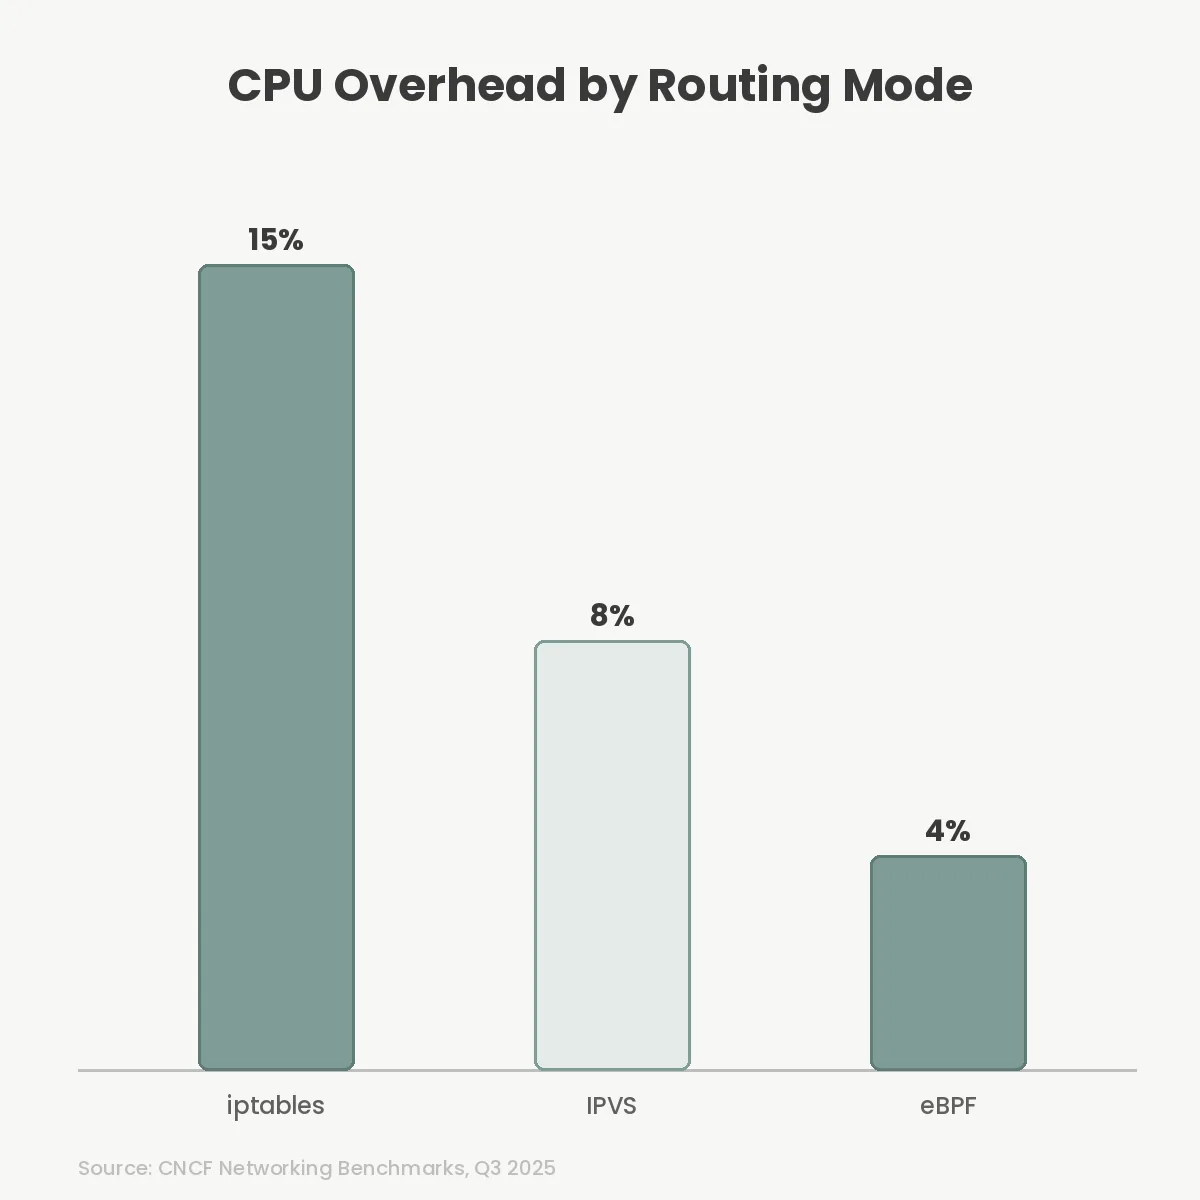
Production benchmarks reveal stark contrasts in hardware utilization when clusters scale. On high-throughput worker nodes handling thousands of requests per second, kube-proxy operating in iptables mode incurs an average CPU overhead of approximately 15%. This penalty scales with both packet volume and the raw count of configured network policies. In severe cases, the Linux kernel spends more time processing netfilter chains than delivering application payloads.
An eBPF data plane typically registers a CPU overhead of around 4% under identical load conditions. This 11% reclamation of compute capacity allows infrastructure teams to downsize worker nodes, lower instance types, or increase pod density per node. The reduction in host-level CPU consumption tangibly reduces monthly cloud infrastructure expenditure while providing additional headroom for application processing.
For teams handling high-throughput streaming connections, the latency variance is equally critical. Sequential processing introduces unpredictable jitter during peak loads. The predictable O(1) lookups provided by eBPF maps stabilize p99 latency metrics. This ensures consistent application responsiveness even during massive traffic spikes, preventing connection timeouts in latency-sensitive microservices.
Despite the performance benefits, eBPF is not a universal requirement for every architecture. The primary limitation is infrastructure compatibility. eBPF data planes require modern Linux kernels—specifically version 4.19 or higher for basic functionality, and 5.8+ for advanced features like modern sockmap support. Organizations running legacy enterprise distributions, or those operating in restricted regulatory environments where kernel upgrades are delayed, may face kernel panics or degraded fallback modes if they deploy an eBPF CNI prematurely.
Operational complexity presents another significant barrier to entry. Troubleshooting iptables is an established discipline with decades of accumulated tooling, scripts, and engineering knowledge. Debugging eBPF programs requires specialized observability tools like Hubble or custom eBPF tracing utilities. If a network policy fails in an eBPF-only cluster, standard utilities like tcpdump or traceroute often provide incomplete or misleading data because the packets bypass the layers these traditional tools monitor.
If a cluster operates strictly under 1,000 services and network CPU overhead is negligible, migrating to an eBPF CNI introduces architectural risk with minimal return on investment. In such cases, switching kube-proxy to IPVS mode—which utilizes O(1) hash tables within the legacy netfilter framework—often provides sufficient scaling headroom without replacing the underlying packet processing paradigm completely.
The most frequent mistake during an eBPF migration is enabling the new data plane strictly for performance without configuring the necessary telemetry beforehand. Because eBPF bypasses standard kernel networking hooks, legacy monitoring agents that inspect netfilter tables will report zero traffic. Administrators must deploy eBPF-native observability stacks, such as Cilium Hubble or Pixie, before shifting production workloads. Failing to do so guarantees operators will fly blind during the first major incident.
Another common failure involves mixed-mode routing configurations. Running kube-proxy simultaneously with an eBPF replacement can cause severe race conditions. Both systems may attempt to rewrite the same packet headers or apply conflicting NAT rules. This conflict results in silently dropped packets, asymmetrical routing paths, and intermittent DNS resolution failures that are exceptionally difficult to trace across distributed nodes.
Finally, failing to tune the eBPF map sizes can lead to dropped connections at peak load. eBPF maps are allocated statically in the kernel memory upon initialization. If the map limits are not adjusted to accommodate the specific scale of the cluster’s connections and endpoints, the hash tables fill up rapidly. The kernel will silently discard new connection requests without sending a reset flag. Proper capacity planning and continuous monitoring of bpf_map memory metrics are mandatory.
Migrating from an iptables-based kube-proxy requires a strictly phased approach to mitigate downtime. The standard procedure begins with deploying the eBPF CNI in strict alongside mode. This allows kube-proxy to continue handling service routing while the new CNI manages pod IP allocation and enforces basic network policies. This initial phase isolates the architectural risk strictly to the policy engine, leaving the routing layer untouched.
Once stability is confirmed, operators enable the kube-proxy replacement feature flag and decommission the legacy daemonset systematically, node by node. This process demands a thorough verification of external ingress traffic, as external load balancers often rely on specific kube-proxy behaviors for node port resolution. Optimizing protocol-level latency at the cluster edge requires the ingress controller to interface seamlessly with the eBPF data plane without routing loops.
Verification requires analyzing the internal service mesh logs and the kubelet network events to ensure that pod IPs remain fully reachable. Infrastructure engineers must validate that cross-node traffic sustains the expected throughput without TCP retransmissions before marking the migration as complete. Utilizing a staggered rollout, while continuously monitoring TCP connection states, prevents cascading failures in production environments.
| Metric | iptables (kube-proxy) | eBPF (Cilium CNI) |
|---|---|---|
| Lookup Algorithmic Complexity | O(n) – Sequential | O(1) – Hash Map |
| CPU Overhead (High Load) | ~15% per node | ~4% per node |
| TCP/IP Stack Traversal | Full traversal required | Bypassed via sockmap |
| Minimum Kernel Requirement | Linux 3.1+ | Linux 4.19+ (5.8+ recommended) |
Replacing iptables with eBPF transitions a Kubernetes cluster from a legacy packet filtering model to a modern, kernel-native routing architecture. The reduction in CPU overhead and predictable latency at scale fundamentally changes how infrastructure engineers calculate node density. If your application relies on thousands of microservices and network latency dictates user experience, transition to an eBPF CNI like Cilium. However, if your environment is stable on legacy kernels and handles low service volumes, rely on IPVS instead of absorbing the operational complexity of eBPF observability.
The primary disadvantage of eBPF is its strict requirement for modern Linux kernels (4.19+) and the operational complexity it introduces. Traditional network troubleshooting tools often fail to capture eBPF traffic, forcing teams to adopt new, specialized observability platforms like Hubble.
IPVS resolves the sequential O(n) lookup problem by using efficient hash tables, but it still relies on the traditional netfilter framework. It cannot bypass the TCP/IP stack for local pod communications, meaning it cannot achieve the throughput improvements native to eBPF.
Cilium was the first major CNI designed fundamentally around eBPF. Since then, other solutions like Calico have introduced alternative eBPF data planes that operators can toggle to replace their traditional iptables routing mechanisms for better cluster performance.
They serve different architectures. DPDK uses user-space polling, which requires dedicating CPU cores entirely to network processing to achieve high throughput. eBPF operates efficiently within the kernel, making it better suited for general-purpose Kubernetes worker nodes where compute is shared.
You Can Get More Information!