AWS Graviton4 vs Intel Xeon 6: The 2025 Architecture Showdown for Web Apps
For most web applications running on Linux, AWS Graviton4 delivers...
Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

We use cookies for our website to give you the most relevant experience by remembering your preferences. By clicking “accept”, you consent to use of ALL the cookies
This website uses cookies to improve your experience while you navigate through the website. Out of these, the cookies that are categorized as necessary are stored on your browser as they are essential for the working of basic functionalities of the website. We also use third-party cookies that help us analyze and understand how you use this website. These cookies will be stored in your browser only with your consent. You also have the option to opt-out of these cookies. But opting out of some of these cookies may affect your browsing experience.
Necessary cookies are absolutely essential for the website to function properly. These cookies ensure basic functionalities and security features of the website, anonymously.
| Cookie | Duration | Description |
|---|---|---|
| cookielawinfo-checkbox-functional | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category “Analytics”. |
| cookielawinfo-checkbox-functional | 11 months | The cookie is set by GDPR cookie consent to record the user consent for the cookies in the category “Functional”. |
| cookielawinfo-checkbox-necessary | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookies is used to store the user consent for the cookies in the category “Necessary”. |
| cookielawinfo-checkbox-others | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category “Other. |
| cookielawinfo-checkbox-performance | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category “Performance”. |
| viewed_cookie_policy | 11 months | The cookie is set by the GDPR Cookie Consent plugin and is used to store whether or not user has consented to the use of cookies. It does not store any personal data. |
Functional cookies help to perform certain functionalities like sharing the content of the website on social media platforms, collect feedbacks, and other third-party features.
Performance cookies are used to understand and analyze the key performance indexes of the website which helps in delivering a better user experience for the visitors.
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics the number of visitors, bounce rate, traffic source, etc.
Advertisement cookies are used to provide visitors with relevant ads and marketing campaigns. These cookies track visitors across websites and collect information to provide customized ads.
Other uncategorized cookies are those that are being analyzed and have not been classified into a category as yet.
Cyberia Tech, Inc. respects your privacy. This Privacy Policy explains how we collect, use, and share your information. By using our services, you agree to this policy. If any other agreements conflict with this Privacy Policy, the terms of those agreements prevail.
Cyberia Tech complies with the EU-US and Swiss-US Privacy Shield Frameworks for handling personal data from the EEA, UK, and Switzerland. In case of any conflict, the Privacy Shield Principles prevail. Learn more at Privacy Shield. Key Definitions
Information linked to an individual, transferred from the EEA, UK, or Switzerland to the U.S.
Data revealing race, religion, health, sexual orientation, and similar categories.
Effective Date: [ 2026 / 11 / 01 ]
Welcome to The Cyberia Tech ! By accessing or using our website or services, you agree to
comply with and be bound by these Terms of Use and our Privacy Policy. If you do not agree with
these terms, please do not use our Services.
Loading
0 %
Your First Piece of the Puzzle in
Business Growth


For most web applications running on Linux, AWS Graviton4 delivers significantly higher throughput per dollar than comparable Intel Xeon processors, driven by its 96 Neoverse V2 cores and 12-channel DDR5 memory architecture. However, infrastructure teams relying on heavily entrenched x86 binaries, specialized vector math workloads, or legacy CI/CD pipelines must carefully audit their dependencies before committing to an ARM64 migration.
The July 2024 general availability of Amazon EC2 R8g instances reset the baseline for cloud-native performance. AWS delivered a processor with 75% more memory bandwidth per vCPU compared to Graviton3, fundamentally changing how data-heavy web applications process requests. Simultaneously, Intel released its 6th Generation Xeon processors (Sierra Forest), utilizing up to 288 Efficient-cores (E-cores) to aggressively counter ARM’s density advantages. The decision between the two no longer relies on a simple cost equation, but rather on how your specific application stack interacts with the underlying silicon cache tiers and instruction sets.
The core proposition of the Graviton4 processor lies in its memory architecture. Web applications, particularly those handling massive volumes of JSON serialization or serving as API gateways, are rarely constrained by raw computational speed. Instead, they hit memory bottlenecks. Graviton4 addresses this by integrating 12 channels of DDR5-5600 memory and providing 2 MB of dedicated L2 cache per core.
When a Node.js event loop or a Go goroutine processes an incoming HTTP request, the processor must frequently retrieve connection state and session data. If that data resides in the L2 cache, retrieval takes nanoseconds. If the processor misses the cache and hits system memory, the thread stalls. By doubling the L2 cache size compared to its predecessor, Graviton4 keeps the working sets of modern garbage-collected languages immediately accessible to the execution units. This hardware design directly translates to reduced tail latencies during sudden traffic spikes.
Furthermore, R8g instances scale much further vertically than older generations. With configurations supporting up to 192 vCPUs and 1.5 TB of RAM, organizations running massive monolithic databases or high-throughput eBPF-based network routing layers can consolidate workloads onto fewer physical nodes, reducing network hop latency.
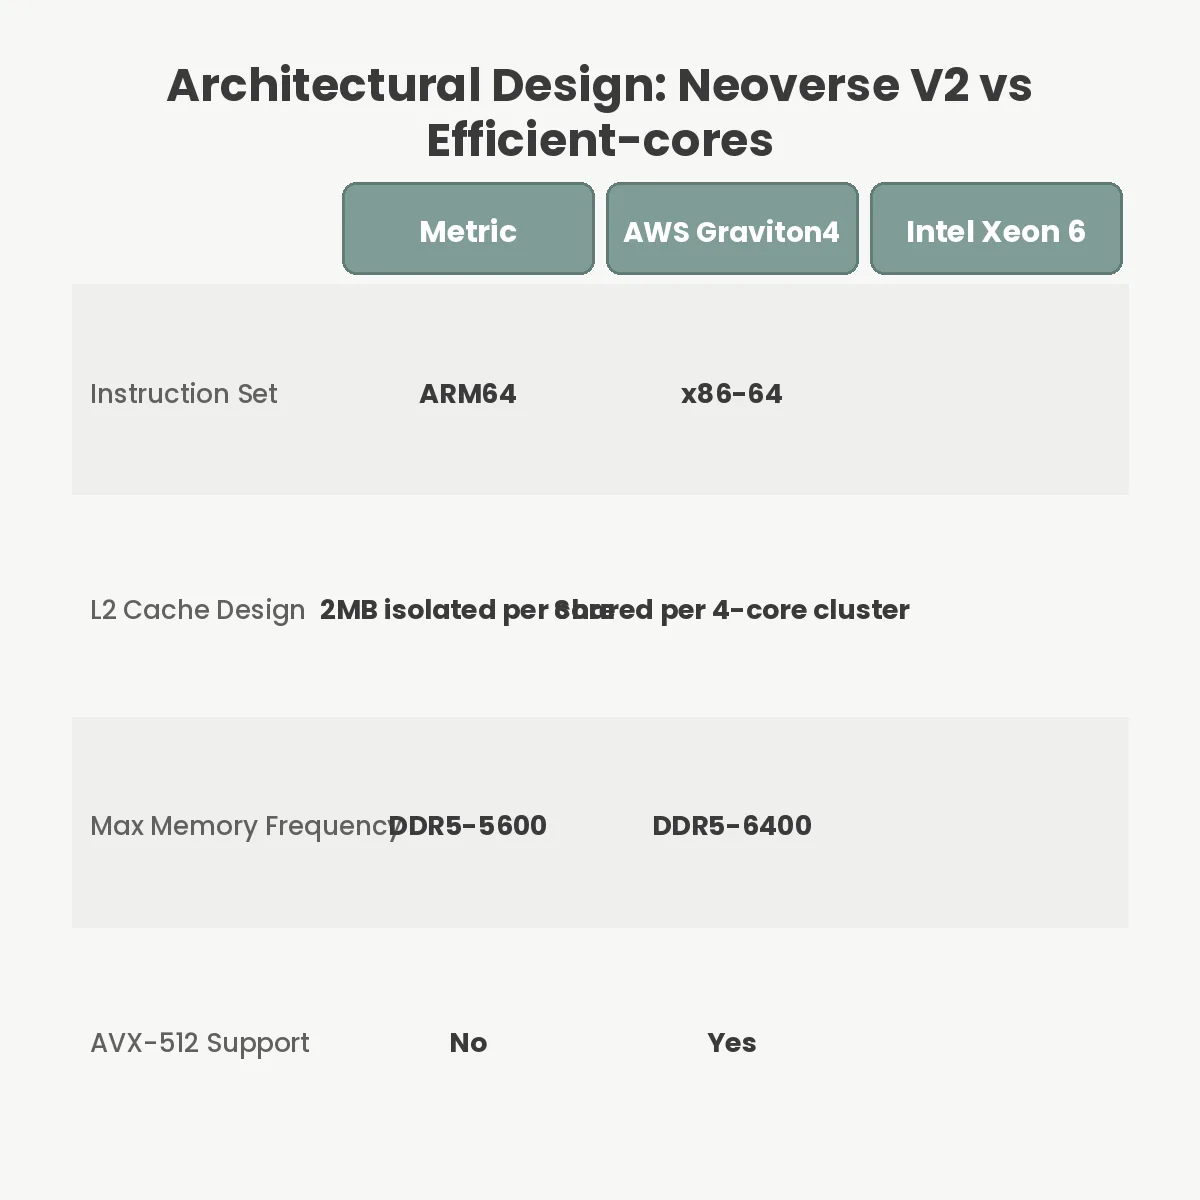
Intel did not cede the cloud computing market. The Xeon 6 architecture, specifically the Sierra Forest line, introduced a radical departure from traditional Intel server designs. Instead of focusing entirely on single-thread performance with Performance-cores (P-cores), Intel packed up to 288 Efficient-cores (E-cores) onto a single processor package.
This design acknowledges that cloud-native web throughput requires concurrency over clock speed. A fleet of microservices operating inside a Kubernetes cluster benefits far more from having hundreds of physical execution threads available than it does from having a few highly boosted cores. The Sierra Forest architecture explicitly targets the exact same scale-out web application workloads that Graviton4 dominates.
For engineering teams, the primary advantage of Xeon 6 is absolute compatibility. It offers high-density computing without requiring a single modification to existing Dockerfiles, build pipelines, or third-party binary dependencies. You gain cloud-native efficiency while remaining firmly within the established x86 ecosystem.
Despite the architectural advantages of Graviton4, forcing a migration under the wrong conditions will degrade performance and inflate engineering costs. The most severe limitation of the Neoverse V2 architecture is its lack of advanced x86 vector extensions, specifically AVX-512. If your web application performs heavy image transcoding, cryptographic generation, or certain types of machine learning inference directly on the web tier, an Intel processor will process those instructions significantly faster.
Similarly, database workloads require careful profiling. While standard relational queries perform exceptionally well on ARM, specialized extensions often rely on hardware-specific optimizations. For example, teams running pgvector for similarity searches must verify that their specific index types and distance functions compile natively and efficiently on ARM architectures before transitioning their primary data stores.
Another absolute barrier involves proprietary third-party agents. Many older security scanners, APM agents, and compliance logging binaries are shipped exclusively as compiled x86 binaries. Running these tools through QEMU emulation or Rosetta on Graviton instances incurs a massive CPU penalty, entirely negating any performance gains achieved by the application itself.
In-memory data stores heavily expose the differences in memory bandwidth between these architectures. A dedicated caching layer spends nearly all its processor cycles reading from and writing to RAM. Graviton4’s 75% increase in memory bandwidth per vCPU makes it exceptionally well-suited for these roles.
When running a high-frequency Valkey or Redis caching tier, the CPU is rarely the bottleneck; the limiting factor is how fast data can travel across the memory bus. Intel’s Sierra Forest counters this by supporting 12 channels of DDR5-6400 memory, offering a higher peak frequency than Graviton4’s DDR5-5600. The technical decision here requires benchmarking your specific cache hit ratios and payload sizes.
If your application serves massive amounts of static configuration data (large payloads), the higher peak frequency of Intel’s DDR5 implementation might provide an edge. Conversely, if your application processes millions of tiny cache validations (small payloads), Graviton’s larger dedicated L2 cache often results in higher overall throughput by preventing the memory bus from being saturated in the first place.
The most common failure mode during a Graviton migration has nothing to do with the application code; it happens in the deployment pipeline. Teams frequently update their AWS EC2 or EKS node groups to ARM64, only to discover their automated builds now take ten times longer to complete.
This occurs when an x86 GitHub Actions runner or Jenkins node attempts to build an ARM64 container image using Docker Buildx and QEMU emulation. While Go or WebAssembly binaries cross-compile natively with minimal overhead, interpreting C++ extensions for Python or Node.js through an emulator is disastrously slow.
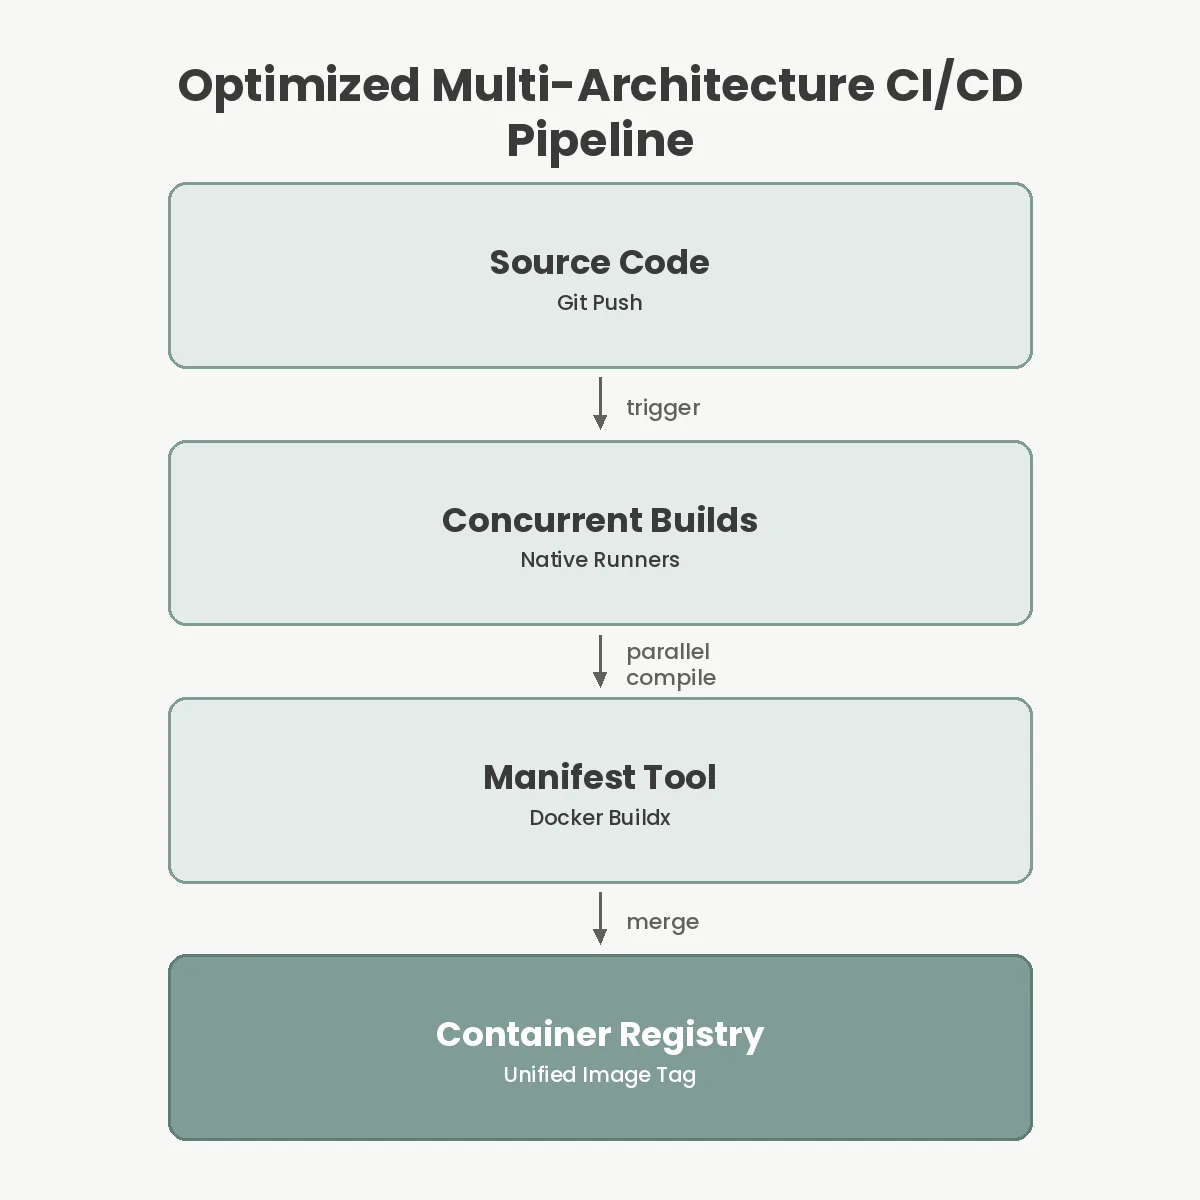
To resolve this, infrastructure teams must configure native ARM64 runners in their CI/CD environments. Building a multi-architecture manifest requires distinct build jobs running on their respective native silicon, followed by a final step that stitches the AMD64 and ARM64 images into a single unified Docker manifest. Attempting to bypass this hardware requirement will paralyze developer velocity.
Understanding the hardware specifications clarifies why these processors handle web traffic differently. The table below outlines the critical differences between the two architectures for web workloads.
| Specification | AWS Graviton4 (R8g) | Intel Xeon 6 (Sierra Forest) |
|---|---|---|
| Core Architecture | ARM Neoverse V2 | x86 Efficient-cores (E-cores) |
| Maximum Cores per Socket | 96 | Up to 288 |
| Memory Support | 12-channel DDR5-5600 | 12-channel DDR5-6400 |
| Dedicated L2 Cache | 2 MB per core | Shared per 4-core cluster |
| Instruction Set Penalty | Requires recompilation | None (native x86) |
Graviton4 enforces an isolated cache architecture, preventing noisy neighbor problems between adjacent cores running entirely different application threads. Intel opts for a shared L2 cache across core clusters, which can accelerate workloads where multiple threads process the exact same dataset concurrently, but risks cache eviction during highly heterogeneous web requests.
You cannot run standard x86 container images natively on Graviton4 without severe emulation penalties. You must rebuild your images targeting the linux/arm64 platform to ensure the binaries compile correctly for the ARM instruction set, preventing significant performance degradation.
Yes, the V8 engine and the Node.js runtime provide full native support for ARM64 architectures. However, if your Node.js application relies on native C++ addons via node-gyp, those specific modules must be recompiled for ARM during the build process.
Building ARM containers on x86 CI/CD runners relies on QEMU emulation, which translates instructions one by one. To resolve this bottleneck, you must provision native ARM64 runners in your build pipeline and assemble a manifest list merging the two architectures.
For standard queries in PostgreSQL or MySQL, Graviton4 reduces latency due to its large 2MB L2 cache and high memory bandwidth. However, databases relying heavily on specialized x86 vector extensions may actually see decreased performance unless specifically optimized for Neoverse V2.
Choosing between Graviton4 and Intel Xeon 6 requires an honest audit of your organizational capabilities. If your workloads are written in modern, memory-managed languages, and your DevOps team possesses the capacity to engineer native multi-architecture build pipelines, migrating to R8g instances will yield immediate technical and financial returns. The Neoverse V2 architecture is ruthlessly efficient for API traffic and caching tiers.
Conversely, if your infrastructure relies heavily on closed-source APM agents, proprietary binaries, or complex C++ machine learning modules, Intel’s Sierra Forest provides an exceptional scale-out upgrade path. It delivers the concurrency required for cloud-native applications without introducing instruction set translation overhead or forcing a complete rewrite of your deployment automation.
You Can Get More Information!