Startup FinOps Strategy: How to Tame Cloud Sprawl Before Series B
A startup FinOps strategy is a cross-functional financial management practice...
Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

Make email marketing simplified

We use cookies for our website to give you the most relevant experience by remembering your preferences. By clicking “accept”, you consent to use of ALL the cookies
This website uses cookies to improve your experience while you navigate through the website. Out of these, the cookies that are categorized as necessary are stored on your browser as they are essential for the working of basic functionalities of the website. We also use third-party cookies that help us analyze and understand how you use this website. These cookies will be stored in your browser only with your consent. You also have the option to opt-out of these cookies. But opting out of some of these cookies may affect your browsing experience.
Necessary cookies are absolutely essential for the website to function properly. These cookies ensure basic functionalities and security features of the website, anonymously.
| Cookie | Duration | Description |
|---|---|---|
| cookielawinfo-checkbox-functional | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category “Analytics”. |
| cookielawinfo-checkbox-functional | 11 months | The cookie is set by GDPR cookie consent to record the user consent for the cookies in the category “Functional”. |
| cookielawinfo-checkbox-necessary | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookies is used to store the user consent for the cookies in the category “Necessary”. |
| cookielawinfo-checkbox-others | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category “Other. |
| cookielawinfo-checkbox-performance | 11 months | This cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category “Performance”. |
| viewed_cookie_policy | 11 months | The cookie is set by the GDPR Cookie Consent plugin and is used to store whether or not user has consented to the use of cookies. It does not store any personal data. |
Functional cookies help to perform certain functionalities like sharing the content of the website on social media platforms, collect feedbacks, and other third-party features.
Performance cookies are used to understand and analyze the key performance indexes of the website which helps in delivering a better user experience for the visitors.
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics the number of visitors, bounce rate, traffic source, etc.
Advertisement cookies are used to provide visitors with relevant ads and marketing campaigns. These cookies track visitors across websites and collect information to provide customized ads.
Other uncategorized cookies are those that are being analyzed and have not been classified into a category as yet.
Cyberia Tech, Inc. respects your privacy. This Privacy Policy explains how we collect, use, and share your information. By using our services, you agree to this policy. If any other agreements conflict with this Privacy Policy, the terms of those agreements prevail.
Cyberia Tech complies with the EU-US and Swiss-US Privacy Shield Frameworks for handling personal data from the EEA, UK, and Switzerland. In case of any conflict, the Privacy Shield Principles prevail. Learn more at Privacy Shield. Key Definitions
Information linked to an individual, transferred from the EEA, UK, or Switzerland to the U.S.
Data revealing race, religion, health, sexual orientation, and similar categories.
Effective Date: [ 2026 / 10 / 28 ]
Welcome to The Cyberia Tech ! By accessing or using our website or services, you agree to
comply with and be bound by these Terms of Use and our Privacy Policy. If you do not agree with
these terms, please do not use our Services.
Loading
0 %
Your First Piece of the Puzzle in
Business Growth


For most web applications, PostgreSQL with the pgvector extension is sufficient for storing and querying up to 10 million vector embeddings, primarily due to the HNSW indexing introduced in version 0.6.0. Dedicated vector databases like Pinecone or Qdrant are only strictly necessary when an application exceeds 50 million embeddings, requires sub-20 millisecond query latency at high concurrency, or relies on distributed, GPU-accelerated infrastructure.
Adding retrieval-augmented generation to a web application forces an architectural fork. You must store high-dimensional embeddings somewhere. The default reflex for many engineering teams is spinning up a managed vector database immediately. Adding a new data store fractures the architecture. It breaks transactional guarantees. You now have to synchronize relational data with vector payloads across a network boundary. That operational tax is high. Measuring whether you actually need a specialist engine requires looking at index mechanics, memory scaling, and data synchronization overhead.
PostgreSQL handles vectors as a custom data type via the pgvector extension. Early versions struggled with performance because they relied on IVFFlat (Inverted File Flat) indices. IVFFlat required the data to be loaded before the index was built, forcing developers to recalculate centroids whenever the dataset drifted. This created severe operational bottlenecks for applications with frequent write operations.
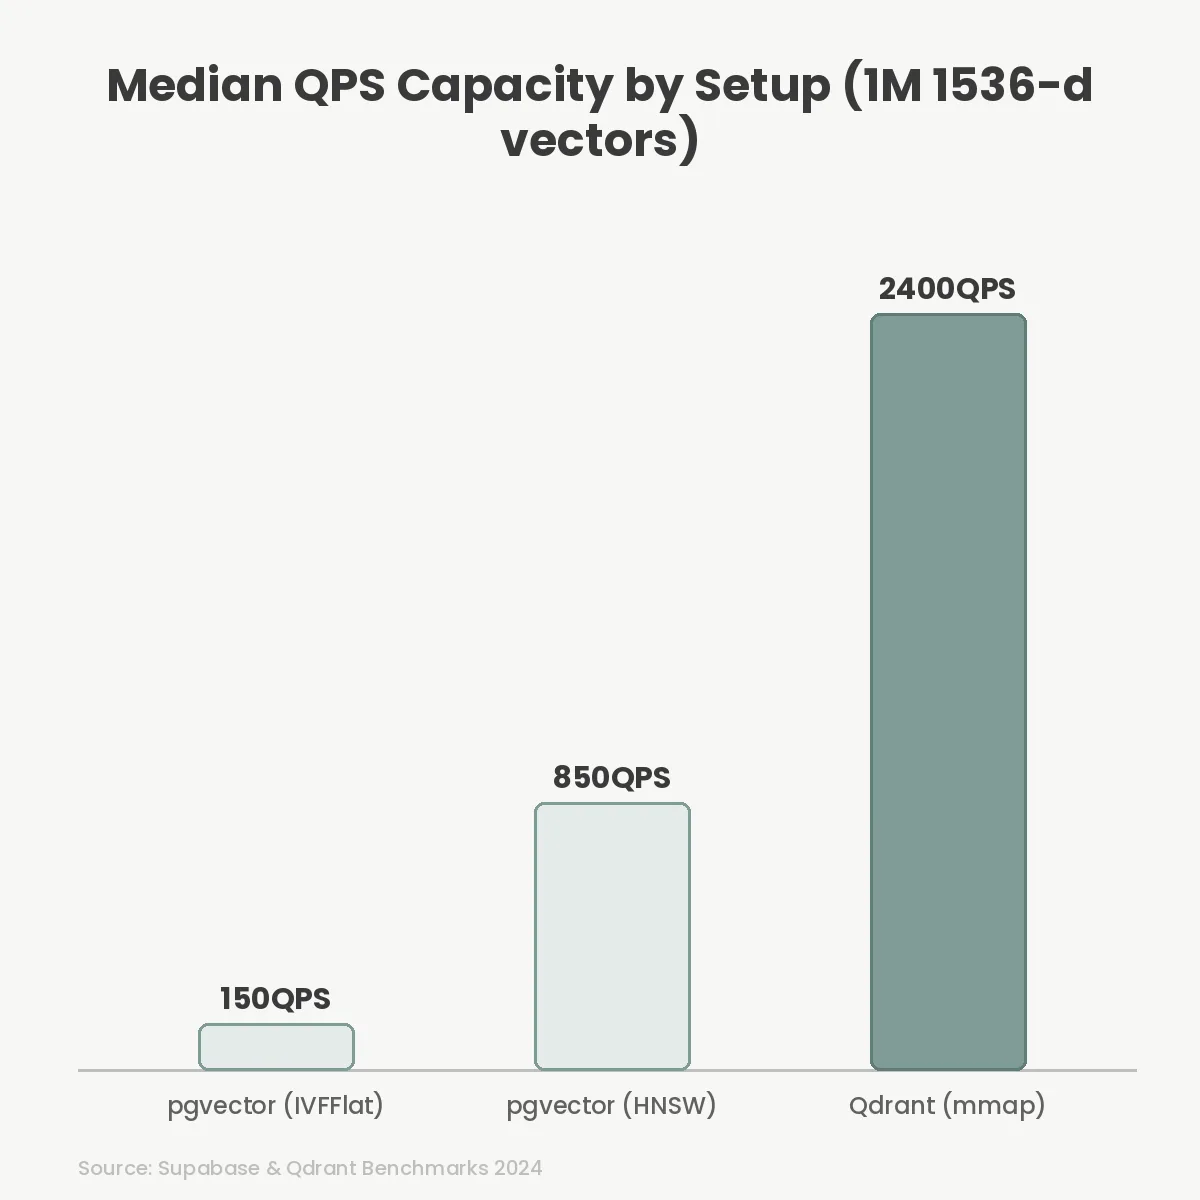
The release of pgvector v0.6.0 changed the baseline. It introduced Hierarchical Navigable Small World (HNSW) indexing. HNSW builds a multi-layered graph that allows fast approximate nearest neighbor search without requiring a pre-training step. It dynamically updates as new vectors are inserted. For standard 1536-dimensional vectors produced by OpenAI’s text-embedding-3-small model, pgvector can now execute sub-50ms queries over millions of records.
Postgres does impose physical constraints. Standard Postgres pages are hardcoded to 8KB. High-dimensional vectors can exceed this, forcing Postgres to compress them or move them out of line using TOAST (The Oversized-Attribute Storage Technique). TOAST lookups incur disk I/O penalties. While newer Postgres versions optimize this slightly, keeping index structures in RAM is mandatory for acceptable performance. If your HNSW index size exceeds available memory, the database falls back to disk, and query latency spikes exponentially.
Dedicated vector databases like Pinecone, Milvus, and Qdrant strip away relational overhead to maximize similarity search throughput. They implement advanced memory management techniques specifically designed for high-dimensional arrays. Qdrant, written in Rust, leverages memory-mapped files (mmap). This keeps its idle memory usage incredibly low—often under 50MB for small clusters—and allows the operating system to page data out to disk predictably without hard out-of-memory crashes.
Serverless architectures have reshaped the cost modeling for these specialists. Pinecone Serverless charges directly based on usage, pricing operations at roughly $0.33 per 1 million read units and $2.00 per 1 million write units. For bursty AI workloads or enterprise AI integration tools that process heavy batch embeddings overnight but remain idle during the day, this decoupled compute-and-storage model is vastly cheaper than running a permanently over-provisioned Postgres RDS instance.
Scale dictates infrastructure. Milvus version 2.4 introduced NVIDIA GPU acceleration for index building and querying. If your architecture processes billion-scale datasets, running multi-vector queries against a distributed Milvus cluster will outperform pgvector entirely. Dedicated engines also native support for sparse-dense hybrid search (like BM25 combined with dense embeddings), which pgvector currently requires complex custom queries to replicate.
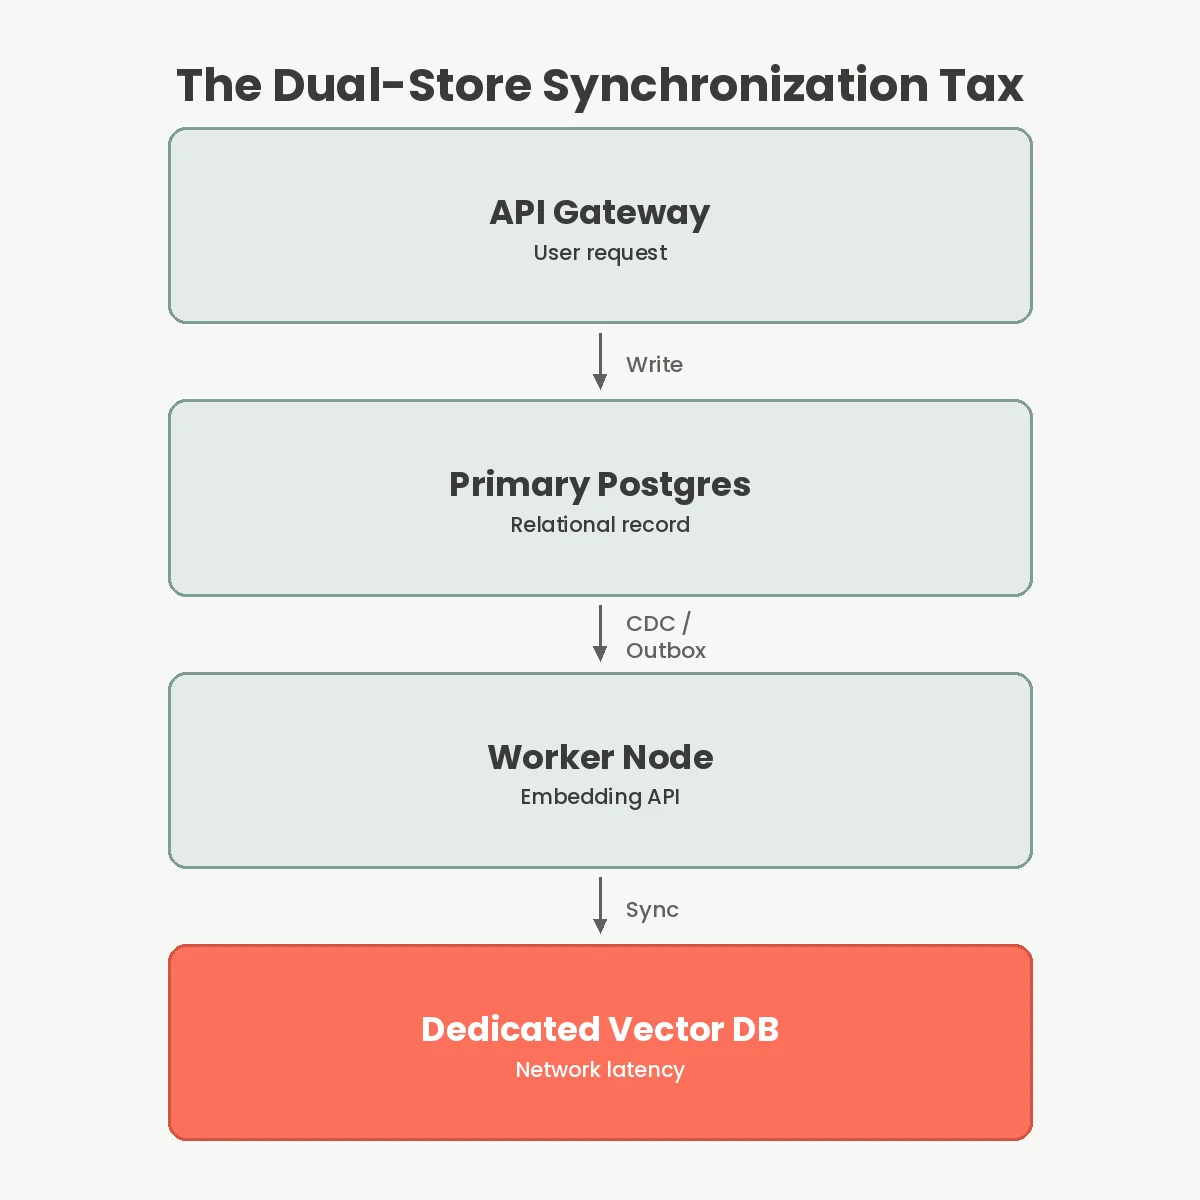
Splitting your data across two stores creates immediate consistency problems. When a user deletes their account in Postgres, the corresponding embeddings must be scrubbed from the vector database to maintain compliance. Doing this reliably requires an outbox pattern, asynchronous workers, and robust retry logic. A dual-store architecture guarantees that at some point, the systems will drift out of sync.
Relying on a single Postgres instance guarantees Atomicity, Consistency, Isolation, and Durability (ACID). You can insert the user record and the embedding in a single transaction. If the embedding fails, the user record rolls back. You avoid building a distributed tracing pipeline just to ensure data actually made it to the vector index.
Introducing a second database also complicates your caching strategy. When querying across two stores, you cannot easily invalidate Valkey or Redis caching layers based on a single trigger. The operational burden of managing migrations, backups, and network policies doubles.
Evaluating these solutions requires mapping them against specific engineering constraints. Latency, memory limits, and maintenance overhead define the boundary of where pgvector stops making sense.
| Database Solution | Index Type | Memory Management | Best Use Case |
|---|---|---|---|
| Postgres (pgvector) | HNSW / IVFFlat | RAM bound (expensive to scale) | <10M vectors, ACID priority |
| Pinecone Serverless | Proprietary graph | Decoupled compute/storage | Spiky workloads, zero-ops preference |
| Qdrant | HNSW (mmap) | Graceful disk fallback | High scale, low memory footprint |
| Milvus | GPU-accelerated | Distributed nodes | Billion-scale, sub-20ms latency |
Cost modeling is highly variable. A self-hosted Postgres instance costs a fixed amount monthly regardless of read/write volume. Serverless vector databases scale to zero, but punish high-throughput continuous writes. If you stream real-time embeddings directly to the client using Server-Sent Events (SSE), the constant read/write cycles against a managed vector database can quickly exceed the cost of a dedicated Postgres server.
Over-indexing is the most frequent architectural mistake. Developers default to indexing every field. HNSW indices are computationally expensive to build and consume massive amounts of memory. Indexing billions of vectors with high connectivity parameters (M and ef_construction) will choke Postgres, blocking subsequent write operations while the graph rebuilds.
Another failure mode is ignoring hybrid search realities. Pure semantic search often returns irrelevant results when users search for exact product SKUs or specific names. Developers quickly realize they need relational filtering (e.g., “find vectors similar to X where tenant_id = Y”). Postgres handles pre-filtering via native WHERE clauses effortlessly. Dedicated vector databases implement metadata filtering, but applying complex relational joins across an external API boundary results in severe network latency.
Finally, teams underestimate the memory footprint of the vectors themselves. Storing 1 million 1536-dimensional vectors requires roughly 6GB of RAM just for the raw data, ignoring index overhead. Provisioning a database instance without accounting for the multi-gigabyte memory requirement of the HNSW graph guarantees constant cache evictions and disk thrashing.
If your application has fewer than 10 million vector embeddings and your team already maintains Postgres, installing pgvector is the correct engineering decision. The performance is completely adequate, and the operational simplicity of ACID compliance far outweighs the marginal latency improvements of a dedicated store.
Move to a dedicated vector database only when Postgres metrics prove it is failing. If your HNSW indices are forcing expensive RAM upgrades on your primary database, or if you require specialized features like multi-vector search and disk-ann hybrid architectures, migrate to Qdrant or Pinecone. Do not pay the dual-database synchronization tax until your scale forces the issue.
Yes, but it requires significant vertical scaling and manual partitioning. At a billion vectors, pgvector’s memory footprint for HNSW indices becomes cost-prohibitive compared to purpose-built distributed engines that leverage optimized compression algorithms and disk-based retrieval.
No. Pinecone handles vector similarity and basic metadata filtering. You cannot perform complex joins, traditional aggregations, or cross-table queries. This forces you to maintain a separate relational database and keep both datastores continuously synchronized.
IVFFlat groups vectors into clustered lists and requires a pre-training step, offering lower memory usage but slower recall. HNSW builds a multi-layered graph for navigation, providing faster search and zero training steps, but consuming significantly more memory.
Qdrant uses memory-mapped files written in Rust. This allows the database to serve queries directly from disk when RAM is full, gracefully degrading performance instead of crashing completely like purely in-memory database engines.
Evaluate your architecture strictly by the numbers. Run the load test against pgvector on your existing database instance before engaging a third-party vendor. Add the specialist tool only when query latency exceeds your application’s defined thresholds or memory costs outpace the pricing of managed vector services.
You Can Get More Information!